

Why docs still need an owner — podcast with CT Smith about WTFM
Note: These shownotes are AI-generated.
- Audio-only version
- Links mentioned
- Topics covered in this podcast
- Narrative essay version of the conversation
- Transcript
Audio-only version
Listen here:
Links mentioned
- WTFM (CT Smith — read the book free online)
- WTFM: A Practical Guide for Standing Up Docs at a Startup (Amazon — paperback and Kindle editions)
- AI usage statement — WTFM (CT Smith — how she used Falconer, Claude Code, and inkling-small on the book)
- Hire a writer — WTFM (CT Smith — the chapter on ownership, the junk drawer, and systems thinking)
- ct smith – docs goblin home (CT Smith’s blog)
- Passo.uno – Fabrizio Ferri Benedetti on Technical Writing (Fabrizio Ferri-Benedetti — co-host website)
- Tech needs humanists more than ever (Fabrizio Ferri-Benedetti, passo.uno — the post Fabrizio mentions at the end)
- Podcast: Writing as telepathy: AI tools, automation, and an intentionally offline life – conversation with CT Smith (Tom Johnson, I’d Rather Be Writing — CT’s previous appearance on the podcast)
- Six new books in tech comm: a roundup (Tom Johnson, I’d Rather Be Writing)
- How the Claude Code team does code review (Addy Osmani, Morgan Westlee Lunt, and Qing Wang, claude.dev blog — the post Fabrizio quotes)
- jdkato/voices: AI writing skills as Vale rules (GitHub — the Voices package CT uses with a Claude hook)
- vale-cli/agent-tools (GitHub — Vale packaged for coding assistants, including the edit-time linting hook)
- Falconer: The source of truth for high-speed teams (the AI writing tool CT used in interview mode to outline the book)
- Neovim (the text editor CT wrote the book in)
- Agent-Friendly Documentation Spec (Dachary Carey)
- Agent-Friendly Docs (Dachary Carey)
- Every Page is Page One (Mark Baker’s blog)
- Thinking In Systems: A Primer (Donella H. Meadows, Goodreads)
- Ezra Klein on AI and gradual disempowerment (Ezra Klein, The New York Times, October 18, 2026 — the article Tom mentions)
- Gradual Disempowerment: Systemic Existential Risks from Incremental AI Development (Jan Kulveit et al., arXiv — the paper that introduced the term)
Topics covered in this podcast
Here’s a list of topics we talked about.
-
Why write a book about docs, and who it’s for — The book came out of a burst of energy after treating sleep apnea, plus friends suggesting a business book about the thing CT already knows. It targets founders, PMs, and early startup hires who end up owning docs without knowing technical writing is a profession, not other tech writers.
-
Keeping a human voice in the age of AI — Falconer’s interview mode produced the outlines, with CT rambling answers in voice mode. After that, she wrote every chapter by hand in Markdown in Neovim, partly on an offline ThinkPad. Claude Code and inkling-small handled conversion to the print, EPUB, and web versions.
-
Timeless principles over AI discourse — The book deliberately keeps AI in a supporting role. Plenty of people already write about AI and docs, and a book about AI goes out of fashion quickly. The aim is to teach the underlying principles of writing so readers can make good choices with whatever AI tools they use.
-
Chunking and writing for agents — CT is building a docs compiler with her own RAG pipeline and a chunker that doesn’t overlap chunks but attaches the section heading to every passage. No chunking strategy works everywhere, though, and her experiments show that fetch-only agents need different things than agents that browse.
-
The context custodian — Docs need one owner with responsibility and authority over them, or nobody investigates when an AI chatbot gives a customer a bad answer traced to a vague doc. AI has empowered people to produce slop at full speed, so ownership becomes a governance problem, not a power grab.
-
Tech writers as consultants who supply templates and skills — In some companies, writers now give product teams templates, skills, and infrastructure while those teams write their own docs. CT ran a version of this model years ago with about 80 contributors, and she thinks it’s where much of the field is heading.
-
A layered pipeline with a human at the end — A Vale hook, directory-level agent instructions, a docs CLI, Opus drafting with Sonnet reviewing, CI, tuned Copilot reviews, and a fixture factory with sandbox credentials all run before a human looks. About 40% of CT’s tickets now run nearly autonomously, starting from a doc plan she approves.
-
Skills that point to the docs — After running about a thousand evals, CT found that the best skills mostly point to the docs and flag the tempting paths that lead agents astray, such as an endpoint with a different auth scheme. A monthly report skill cut an eight-hour job to minutes, but every skill that isn’t a throwaway needs maintenance.
-
Gradual disempowerment and staying sharp — When a skill can turn fifty bug tickets into fifty PRs, writers risk reviewing work they don’t understand and simply routing it to SMEs. The counterweight is knowing the product well enough to spot problems, never passing along unreviewed AI output, and working the occasional ticket by hand.
-
Systems thinking and silo bridging — Systems thinking is the top trait CT would hire for in a first docs writer. Frontier models still fail at information architecture, and cross-product workflows fall through the cracks because of Conway’s law. Writers who understand how the pieces connect, and maybe have a humanities background, can bridge those silos.
Sponsored
Narrative essay version of the conversation
If the podcast were an article, this is what it would read like.
Someone still has to own the docs
At a four-person startup, nobody has the title of technical writer. A product manager notices that customers keep asking the same question, writes down the answer, and before long that page turns into the start of a docs site. The person who wrote it didn’t plan to own documentation, and they might not even know that technical writing is a profession with its own practices. WTFM: A Practical Guide for Standing Up Docs at a Startup is written for that person, and its central argument holds up well beyond startups. Docs need an owner, and AI tools probably make that need more pressing, not less.
It’s tempting to assume the opposite. If anyone in a company can generate a page, a section, or a full guide in a few minutes, why would the company need someone dedicated to docs? The answer shows up when something goes wrong. Suppose an AI chat assistant tells a customer they can do something the product doesn’t support, and the customer acts on it. Who investigates the conversation? Who traces the bad answer back to the vague doc it came from? And who explains why the company now owes that customer money?
If nobody owns the content, the failure belongs to a process that works most of the time, and the edge cases fall between silos where nobody is looking. As the book says, “When you expect everyone to own a system, no one does. Without a strong holistic owner, your docs end up becoming a junk drawer.” In other words, ownership is a governance problem as much as a writing problem.
The role that grows out of this looks more like a custodian than an author. One job title floated in the conversation is context custodian, meaning someone with responsibility and authority over how content reaches the channels where internal and external customers find it. That role doesn’t require writing every word. A model where engineers and product managers contribute through templates, and a writer polishes and publishes, has worked for years, well before LLMs got cheap. At one company it scaled to about 80 contributors working with one outnumbered writer. What changes with AI is that templates become the first layer in a larger stack of tooling.
That stack has several layers, and each one catches something the previous one misses. A Vale hook makes Claude check its prose against a small set of rules before its output reaches a ticket or a file. Directory-level instruction files give different guidance for API definitions, guides, and diagram source files. A docs CLI generates new pages from templates, so the model fills in a structure instead of improvising one, and it bundles several validations into one command.
A draft from one model goes to a second model for review, then to CI, and then to an automated PR reviewer that had to be taught how to review well. A fixture factory gives the agent sandbox credentials so it can run the API calls itself and confirm the behavior before a human sees the change. Nothing merges until a human looks at it, and behavioral changes need an SME’s sign-off.
With this setup, roughly 40% of tickets run nearly autonomously. The writer approves a short doc plan for each one, goes to lunch, and comes back to pull requests that get the same review a junior writer’s work would get.
Skills fit into this picture well, partly because skills are essentially instructions, and instructions are what technical writers already produce. After about a thousand evals spent watching agents choke on predictable problems, a useful design principle emerges. A skill should mostly point to the docs, and it should spell out the places where the tempting path is wrong. Authentication is a common case. An agent tries a bearer token on an endpoint that uses a different auth scheme, fails, and has no way to know why unless something tells it.
Internal skills pay off too. A monthly metrics report that used to take eight hours now takes a few minutes to kick off, plus a review pass to spot-check the numbers and rewrite the summary so it doesn’t read like Claude wrote it. The catch is maintenance, since any skill that isn’t a throwaway needs the same upkeep as any other doc.
Where it gets uncomfortable is velocity. What happens when a skill can turn fifty bug tickets into fifty pull requests in a couple of hours? Can a writer meaningfully review changes they never did the cognitive work to understand? And if the writer mostly routes each change to the right SME, what are they contributing? The term gradual disempowerment, which comes from AI safety research, describes this drift fairly well. Each handoff seems reasonable, but over time the human becomes less capable.
One response is a personal discipline more than a rule. Know the product well enough to recognize when something looks wrong and when to tag someone in, never hand an SME unreviewed AI output, and occasionally pull a ticket from the queue and work it by hand, git commands and all, to keep that part of the brain in shape.
There’s a reasonable counterargument, though. The Claude Code team at Anthropic wrote that nobody on their team keeps a complete mental model of Claude Code, and that they don’t think anyone needs to. Accepting partial understanding might just be part of working in this era. It’s also worth admitting that this kind of orchestration depends on years of doing the work manually, which makes the path harder for people entering the field now.
The two positions might be closer than they look, since both aim at understanding how the pieces fit together rather than mastering every piece. That points to systems thinking, which the book calls “probably the biggest thing” to look for in a first docs hire. Frontier models still struggle with information architecture, even on a project of about 200 pages that already has skills and guidance written for it.
Cross-product workflows are another weak spot. Because of Conway’s law, each team documents its own product, and almost nobody documents how three products work together. As every team’s Claude starts talking to every other team’s Claude, somebody needs to know where the connections are. For anyone who wants to build that skill, Donella Meadows’s Thinking in Systems is a good place to start, and a background in the humanities, such as philosophy, might help more than people expect.
Transcript
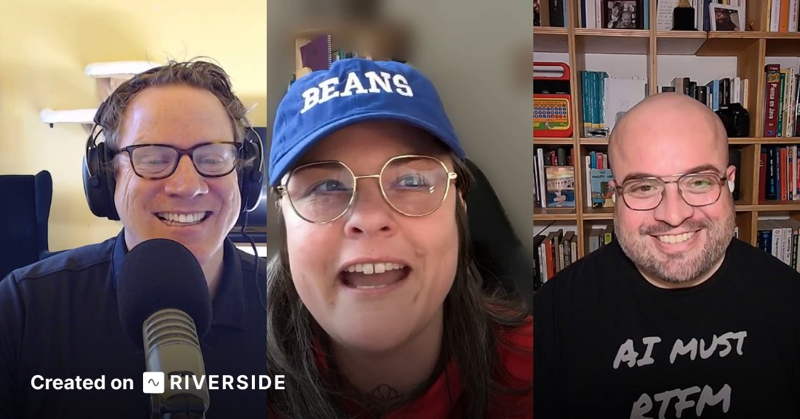
Tom (00:00)
Welcome to another podcast. I’m your host, Tom Johnson, also Fabri Ferri-Benedetti. And today we have…
Fabrizio (00:06)
Hey there.
Tom (00:07)
We have CT Smith as our guest. We’ve had her before, and we’re bringing her back because she has written a really good book, WTFM: A Practical Guide for Standing Up Docs at a Startup. WTFM, what does this stand for?
Fabrizio (00:27)
Well, it’s almost like…
CT (00:27)
Fabulous manual.
Tom (00:29)
Okay. That’s what those asterisks…
Fabrizio (00:31)
Yeah, right. R is here, W is here. RTFM, so…
CT (00:33)
Yes. I think, yeah, so same idea. Write the f… the frickin’ manual, the fabulous manual, however vulgar you want to get with it. There’s a lot of ways it could go.
Tom (00:44)
Which is a play off of a more traditional one, RTFM, right? The terse response when people are asking how to do stuff and you’re like, hey, just go read the docs. But now you’re like, just write the docs. Well, and Fabri, I saw you were in the acknowledgments on the last page, so you must have had some kind of input on an early draft.
Fabrizio (01:06)
Well, I think it was… yeah. And you know, I love the idea, I love the title. I just tried to provide some general advice. Overall, I really love the book. I think it has the right format for this era, because people tend to get impatient quite fast. I think it’s perfect. It’s easy to consume, it has very strong messaging, and it’s also irreverent, which I love in a book. So there you go.
CT (01:37)
Yeah, Fabri gave me a really great tone check, because I was at the point where I was like, why did I even write this? I don’t want to release this to anybody. This is garbage. And I was like, okay, if Fabri thinks it’s okay, I’m gonna just go do it. And he gave me the courage to continue.
Tom (01:52)
Well, I thought your voice was remarkable in this. It was very enjoyable, it was lively. You could tell there was a voice and a cadence and kind of a snarkiness in places, right? And playfulness. I love the length too. Gosh, a hundred pages is perfect. You read it in a couple of days. It’s easy to read and just enough to, I don’t know, open the door on a lot of topics without requiring a massive investment of time.
CT (02:25)
Thank you, that’s exactly what I was going for. So hearing it from technical writers makes me very happy, ‘cause that means I did exactly what I set out to do.
Tom (02:34)
Yeah, and I’ve got a bunch of questions, mostly from notes from the book and so on. Let’s start out with the point where you just told us what you intended to do. In the last few months, I’ve seen multiple books come out. We’ve seen, I don’t know, three other books recently published in tech comm. Is there a trend of tech writers trying to suddenly justify the profession, or why are people starting to write books? Why did you write this book?
CT (03:11)
So I can’t speak for why others are doing it. I think that generally in the profession there is kind of a vibe that people need to understand what we’re doing. Because, you know, a lot of AI-loving C-suite folks are coming in and going, we don’t really need docs, AI can do the docs. And then they figure out the hard way that people who know how to handle docs also probably need to be involved with AI. So I do think there is a general urge a lot of tech writers are having to justify the profession. That’s not why I did it. I did it because I got a CPAP and started sleeping and suddenly had all of this creative energy to spend. So I just got a weird second wind, and I was like, I need to write a book. I’d always wanted to write a book, and I was asking my friends, what should I write a book about? And they were like, well, write a business book, because I’m not a fiction person. And I was like, well, I don’t know anything about business. And they’re like, docs, dummy. You write about doing the thing that you like doing. And I was like, okay, I could probably swing that. And so it took me another three months of indecision before I finally just decided, okay, I’m just gonna do it this year. And so I did it, and it’s done. Probably won’t do it again, though. It was very stressful.
Tom (04:28)
That’s really interesting. I had no idea. So a CPAP machine gives you energy, now you’ve got the energy to actually write, and you say, I’m gonna write something, and here’s what I know. I love it. Okay.
CT (04:41)
Apparently I had sleep apnea and didn’t know it. And then once I started sleeping, I was like, wow, people, I’m awake in the morning. This is awesome.
Fabrizio (04:48)
Were there people at some point that said, no, let’s turn off the machine, because she has way too much energy or something?
CT (04:53)
You know, my family might feel that way, because I’m like myself, but I have more energy now. So I’m definitely terrorizing everyone that I know with my big ideas.
Fabrizio (05:06)
Well, Tom, what do you think? I mean, there’s a lot of books out there right now around tech comm and docs, etcetera. But what I really loved about CT’s book is that it addresses a different-than-usual audience. I’ve seen lots of books for tech writers, written by tech writers, addressing other technical communicators. And also at conferences, etc. It’s good. It’s a nice thing, right? But I feel like it’s kind of redundant. We know it’s important. We know it matters. We kind of know all this already. It’s like reinforcing the same message over and over. But addressing business people, that’s kind of fresh, right?
Tom (05:50)
Yeah, yeah. And near the end you say that you wrote this book for non-documentation people, people who aren’t already tech writers. So I was curious about that, and I was curious, who are these people? I’ve always worked at companies where they pay technical writers, so I’ve never really had to fish around for, I don’t know, the role itself. But I felt like even though that may be the primary audience, it’s also very helpful for tech writers. I found the sections on site accessibility for agents super helpful. It’s something I’m going through right now. I was taking a ton of notes, had a lot of questions. So it’s probably not just that audience. It does cater to a lot of different roles.
Fabrizio (06:39)
Yeah. What kind of stakeholder did you have in mind, CT, when you wrote it? Because there’s a certain goblin energy, as you would say, right? So what kind of person did you have in mind when you wrote the book?
CT (06:50)
My goblin energy. So my ideal customer for the book, which I also put online for free because I honestly didn’t want anybody to pay for it. People did, though. It was weird. My ideal customer for this was actually people at early-stage startups. You normally have a support person pretty early on, and you might have a marketer, you might have a couple of salespeople, and then customers start asking for docs. And there are people that have founded companies that don’t even know that technical writing is a thing. So I really wrote this for those people, and for the people who are early hires at a startup where they end up having to own docs even though it’s not something they know how to do. They’re just like, okay, well, the customers keep asking for this one thing, so I’m just gonna write it down. We’re gonna have to start a site. And I’ve seen a lot of really good efforts at documenting things by people who aren’t technical documentation people. And I go, okay, well, let me give you a little something to tide you over until your company has headcount, or you have the resources to hire a professional, or there’s enough need for the professional to come in. So I was kind of trying to address a gap. I have a lot of friends now who are at startups who are like, yo, can I get a consult with you? I’m a product manager here. It’s like a four-person company. I’m writing all these docs. I don’t know what I’m doing. And so I’ve talked with my friends about, here’s what you do. This book is kind of born out of having done it a bunch of times, even outside of tech. I only listed my tech experience in the book, but at every job I’ve ever had that wasn’t food service, because I’ve had a lot of those jobs too, I have had to stand up documentation for an org. I was a warehouse manager and a purchaser. I had to write documentation on how to manage the warehouse, and I had to go into the stores and write documentation on how to use the POS system, because it was from 1985. And when we got a new POS, I had to write instructions for that, and opening and closing procedures, and so on and so forth. So I’ve done that multiple times in different forms. My favorite, though, is in tech. I don’t really like doing process for warehouses and things. So I wrote it for every person that I’ve ever met that’s been in that situation. Technical writers were definitely not my audience here. I don’t want the smoke. I don’t wanna have to argue with fellow tech writers about my strongly held opinions about tech writing. I mean, I’ll argue with you guys if you want to, but I wanted to focus on a market that tech writers don’t normally talk to. Also, selfishly, once I’m done doing startup stuff, I wanna be able to glide into consulting. I don’t know when I’m gonna be done doing startup stuff, but eventually I’m gonna wanna be done, I think. I don’t know, we’ll see. But I wanted a way to springboard into that later, and so I figured I needed to build an audience, and a book is a way to do it.
Tom (09:56)
We talked about this at the start, that I thought the voice came across really well in this book. How do you preserve voice in an age where AI is so ready to take over the writing? Tell us a little bit about your writing process and how you preserved voice.
CT (10:13)
Well, it’s my voice because I physically wrote the book myself with my brain, and I didn’t use AI to write the content. For this book, what I did was I used Falconer, which is an AI-powered writing tool. I love Falconer. I can talk about Falconer all day. What I did was I went in and I said, hey, I’m gonna write a book about this. Here are the boulders that I want to include. Please interview me, because I need to generate a general outline. I put it in interview mode, which I prompt in a way that makes it interview me. It asks a question. I then use voice mode to ramble my answer directly to it. And then it’ll go, hmm, good, okay, and then this. And then I’ll ramble again. And at the end, you get an outline. So I did a master outline, and then I did an outline for each of those chapters. What ended up being the book looks very different than that initial outline, but that initial outline really helped. From there, I just took the outline and went to my text editor. I wrote a book in Neovim, which is insane, but I wrote the whole thing in Markdown. And then I used Claude Code and another model, inkling-small, via API, to handle a lot of the book conversion. I laid out the print version myself. I also did the EPUB version, which was all a learning curve, and then I did the website as well in tandem. So I did all three outputs at the same time, and I would randomly check just to make sure that everything looked right. It was a lot of work. But that’s how I preserved the voice, is that I actually sat down and did the writing myself. Offline, actually, on a… where’s my ThinkPad here. I have a ThinkPad that’s nerfed, and I wrote it on this.
Tom (12:01)
I don’t even know what Neovim is. Are you talking about the Vim editor? Like a terminal? My God.
Fabrizio (12:04)
I love it.
CT (12:08)
Yeah. It’s Neovim, it’s like a new Vim. Yeah.
Tom (12:13)
Okay. Hardcore.
Fabrizio (12:14)
Serial hacker there.
CT (12:16)
Zero distractions, though, is why I wanted to write that way, and I’m so used to writing in a text editor at work that it felt very natural for me. So I don’t know, did I answer the question? It was a lot of words to tell you that I wrote the book, and that’s why it sounds like me.
Tom (12:29)
Yeah, no, I think it’s cool. One other high-level comment. If you write a book today about tech comm, there’s gonna be a huge tendency to bring in AI and how AI has changed everything. You could write the whole book about AI and its influence, but you seem to push back on that and really insist on some basics. There was even a section about clarity. Did you have a larger intent to not let the topics be overrun by AI, or what was your larger thought around that?
CT (13:10)
My larger thought around that was there are a lot of smart people right now writing about using AI with docs. And for my target audience, I wanted them to understand the underlying philosophical principles of writing so they could make good choices with AI. I’m not saying I couldn’t write an entire book on docs and AI at this point. I’m gonna start blogging more, I promise. Now that the book’s done, I can do stuff that’s not the book. But I didn’t want to write an entire book about that, because there’s so much discourse already. I really wanted to focus on, here is the bare minimum information you need to do a good job with docs. And so that’s why I did it that way.
Tom (13:57)
Yeah. Now, I think in places, though, you really have to address the impact of AI. And one of those areas, I mentioned this earlier, that really caught my attention was how you make your site accessible to AI. Specifically, how you chunk up sections. One of the core philosophies is that you write so that people can start wherever. They don’t have to start from page one. Every page is page one, as Mark Baker would say. But now if you’ve got AI chunking up your content and feeding it into its vector database and doing relationships, don’t you have to understand how those pieces can be broken and fragmented off? You have to have headings that are super specific. Don’t you have to write with a whole new set of constraints?
CT (15:03)
I think so. But it also depends a lot. For example, I’m working on a docs compiler that I’m building right now called Shoal Run, just for fun. It’s like a tech writer’s art project, you know? We go a little crazy sometimes and we have to build crazy stuff. And I wrote a chunker, because I wanted to make my own RAG pipeline just to see if I could do it and see how search works. I needed to get inside of it and figure it out and wear it like a skin. And I wrote a chunker that actually doesn’t overlap. With some chunking strategies, they’ll overlap chunks, and that’s easier to match up. Instead, what I did was I made it map the headings to each passage. So now every passage that comes from a section has the heading included, and there’s no overlap. But that is a function of how I write and how I think technical writing should be done. Again, every tool is different. If you’re using a vendor, you need to understand what their strategy is, because I can’t blanket-recommend one chunking strategy. It just depends on what the rest of your pipeline is doing with it. Again, this is part of the reason I’m working on this crazy project, is because I want to understand fully where all the edges are on all of it, so I can give better recommendations to people.
Fabrizio (16:12)
So it’s interesting, because the tool you’re building is opinionated. And, you know, that’s wonderful. Connecting back to the previous question, I think talking about AI right now is talking about the role of the human. I’ve sent you this link. This is a recent blog post the Claude Code team at Anthropic published about how they do code reviews. And it boils down to, first, they talk about the scarce resource, which is human time and attention, and they’re very mindful about that. And then there is the thing, just three words that I loved, which is, there you go, direction, taste, and scope. And I think those three words really summarize what this is all about, like what you bring as a tech writer to a startup. It’s not the latest technique or knowledge. Yeah, of course you bring knowledge about how to use AI tools, but ultimately it’s the direction, the intent, and above all your taste in docs. And I think everything else cascades down from that.
CT (17:38)
Yeah, that’s great. I’m not the only one talking about this kind of stuff. And I kind of bring it up… I have a lot of goblin energy around it, and sometimes I just don’t have the patience for those conversations. I’m like, it’s obvious, idiot. It’s obvious where the human comes in. But yeah, so Tom, to go back to your question, it really just depends on what you’re using, and I am not gonna claim that I know exactly how to write for every agent in every situation. They more or less need similar things, I’m finding. But I’ve also been running a bunch of experiments. And of course, Dachary’s got all of her agent-friendly stuff going on too. My experiments have shown that what a fetch-only agent needs is very different than an agent that is actually reading stuff on the web versus trying to just fetch something. So there are a lot of variables at play. It’s very complicated. And I’m not gonna say that there’s a universal fix. I think that there are things that we can do, and most of them boil down to using good writing practices, like good, timeless technical writing principles. That’s why I focused so hard on it and kind of threw the AI in there to keep people interested and help them connect those ideas together. But I didn’t want it to be a book about AI, because it’ll go out of fashion very quickly.
Tom (18:58)
Well, speaking of those principles, and touching upon what Fabri was mentioning, this sense of ownership seems to be very important. So many different people in an org can use AI tools to write, and they can generate, I don’t know, a page, a section, whatever they need. But you said that you really need to have a technical writer who owns the content. Why is that important? What does it mean to be the content owner, and how does that prevent the junk drawer that you referenced in the book?
CT (19:33)
Man, this is my favorite subject. Why it’s important to have an owner is because someone has to be responsible for it. If it doesn’t have an owner, if it doesn’t have a custodian, so to speak, in the sense that you have custody of that output, then it’s nobody’s problem. If the docs are wrong and a customer has a problem, there’s no one to hold accountable. You’re gonna point at a process that is working 90% of the time. Who’s gonna catch the edge cases? Who’s gonna make sure that things that fall between silos… who’s gonna make sure that all of that is cohesive? And I think that the way to do that is having one person who is the custodian. If I could pick any job title, I would probably pick context custodian or something like that. Because that’s how I’m looking at all of this. With AI, we’ve empowered people who could barely string together coherent Slack messages to tell me what they need. We’ve empowered them to full-speed slop cannon, nonstop, Opus. Yeah. Yes, we’ve empowered meat proxies.
Fabrizio (20:39)
Right. We don’t want to be meat proxies, that’s the thing. No meat, right? Yeah.
CT (20:48)
And I think having a human in the loop who owns, who has responsibility and authority over how that content makes it into whatever channels it makes it into to be distributed to internal and external customers, I think that’s critically important, because it’s a governance problem, among other things, obviously. And it’s not because I’m a power-hungry tech writer or anything. I don’t want anybody to message me ever at work. Please don’t talk to me. I’m just kidding.
Fabrizio (21:15)
Power-hungry tech writer is kind of an oxymoron, I think, right?
CT (21:18)
I know. I’m not power hungry. I’m not trying to be important. I just really like information being controlled and in sync and up to date and, like, good. And if there’s a problem, say your AI chat is giving people out-of-pocket answers. “Well, the AI chat told me I could do that.” If nobody owns it, then who goes and investigates that trace? Who goes and investigates that conversation and says, here is where your chatbot got an out-of-pocket answer. This doc is very vague, and that’s why it interpreted it in a way that is wrong, and now we owe the customer thirty thousand dollars. Somebody has to be in charge. And I think that that job is for a human. There has to be a human with taste and direction and discernment and all of that. So that’s what I think, Tom.
Tom (22:07)
I a hundred percent agree. Anybody who’s navigated an internal wiki, you just see so many of the problems of ownerless content. Half of it’s out of date. You know, it’s terrible. Anyway, we don’t have to keep going down that path. I wanna get your opinion on a scenario I ran into, I don’t know, six months ago. A couple of tech writers that I know who are at, like, Amazon reached out and said, hey, we’ve had this huge pivot, and now we’re a tenth of our size, or a fifth of the size. And so their strategy is now the tech writers are more like consultants to all these different product areas. The product areas are in charge of writing their docs, with the tech writer as a consultant. And I think that strategy has morphed into tech writers providing templates, agent skills, and other sorts of infrastructure that they hand off to these many different teams to do the writing. Do you think that’s a good model, or is that gonna be problematic?
CT (23:14)
I think it’s gonna be problematic for writers who don’t want to do that. That is how I see things going. Four or five years ago, when I was at a different company, before the LLMs got cheap for everybody and appeared, I basically did that. I gave engineers and product managers templates, and they had to open PRs, and then I got everything polished up and published, because I was outnumbered. By the time I left that company, I was managing like 80 contributors, which was great. I think that is a model that is sustainable for a lot of businesses. Do I think it works for every single business? Probably not. I’m not like a McKinsey guy or whatever, so I can’t tell you. I will say that I want to work places where that is the model, because that’s what I want to do at this point. I want to use my years and years of expertise getting everybody else organized. I don’t need to write the content anymore. I can teach you how to do it with AI tools. And somebody’s gonna look my address up on the internet. Some mad tech writer is gonna be very mad at me for saying that. But I think that’s the way it’s going for a lot of places, and I think it behooves you, if you are a writer, if you wanna stay employed, to maybe learn how to do that.
Tom (24:32)
Well, two strategies then, if that is gonna be a potential approach. You mentioned in the book that you could set up a CLAUDE.md or AGENTS.md file that would have rules or some kind of guidance, so that when people do write and contribute, maybe it catches their errors and so on. Can you talk about that strategy?
CT (24:52)
Yes. Yes, I can. If you’re familiar with Vale, right? The Vale linter? Everybody loves Vale. The maintainer has released something recently called Voices, and it’s a special package of Vale styles that you can then invoke in a Claude hook. So it makes Claude correct itself before Claude’s output reaches your Linear issue or ticket or anything that you’re using Claude to write. For me, this is a multi-stage approach. I do use the hook at work whenever I’m having Claude author things, because a lot has changed since I was on in January. I think in January, Claude Code was still API-metered usage. It was still very expensive. And then they added it to Pro subscriptions. And so I started using it as my base of operations. I don’t even interact with Falconer anymore. I’m interacting with Falconer from the MCP inside Claude Code, where I’m doing all my work, and the Linear MCP pulls my ticket issues and stuff, and I am piloting Claude Code like a mech, right? And what I really like is I hooked the hook up, and now Claude writes better tickets. It doesn’t Claude-slop them. We also have skills for how to write a ticket. I also have directory-level instructions for different content types. For example, whenever I’m having Claude write OAS, like OpenAPI specification stuff, in that OAS folder there is a specific agents instruction file that will tell it, hey, when you change something, remember this will trip you up, and make sure you always run this particular validation before you try doing the next step. So instructions like that. Our API definition folder has its own instruction file, and then guides have a different one, and then we have our diagram source files, which have their own instructions. So it’s a combination of using hooks that are available to you, like telling Claude, hey, don’t say anything until you first run it through Vale, and then you can say something. There’s a blog post somewhere on Vale’s site that explains how to do it. It’s miraculous.
Fabrizio (27:05)
I think this is a very solid approach. You’re essentially codifying your taste in some sort of rubric that both humans and the AI can follow. But what I was wondering, though, is do you also then have an agent in the pipeline review that downstream? Because on one hand, you ensure that production has those guardrails, either via hooks or skills that the contributors must use. But you know how trust works, right? So I guess you also want to make sure that at the end of the line there’s some kind of safety net, maybe in the form of an agent in CI, right?
CT (27:41)
Yes. It’s me. Well, so the way I do it… now I’m getting really excited, because this is a thing that I really like doing now. This is what I want my job to be. So you’ve got the hooks. You’ve got Claude not messing up from the gate, right? And that’s a smaller subset of Vale rules with specific things that keep Claude from sounding like slop. Then we have a CLI for the doc tooling. I’m gonna do this everywhere I ever work. You build your tools. So I have checks built into there. It may be just an alias for like three validations I want to run and also the Vale check. And then Claude has instructions to run Vale before you do X, Y, and Z, and then fix anything higher than an info. You have to fix warnings and errors, right? And if it’s weird, for example, if it’s a literal error message, leave it alone. We don’t mess with those. We document them as they come. And so from there, my process is, because I do have Claude Code doing about 40% of my work nearly autonomously now. Like 40% of my tickets, not my work. Let me be clear about that. Claude Code knows the process. I like to work with Opus now that they fixed it. Five is not as bad. Like, 5.5 is good. I have Opus hand off to Sonnet for a review, and I’m not involved in this at all. This is the rule. It follows this process. Sonnet first reviews, right? And they are all running Vale. They are running all of our pre-flight validation, as we call it. There’s a lot of little checks that we have it run to make sure everything’s formatted properly, et cetera. And then it goes to CI. And then the org has Copilot review set for every PR. I wrote rules for Copilot, because Copilot was so out of pocket when they first turned it on. I was like, I’m gonna burn this company down, turn that off.
Fabrizio (29:35)
Yeah, I remember.
CT (29:37)
But I figured out you could tell it how to do a good review. So I went and I fixed Copilot, and now Copilot is like a third pair of eyes. No one is allowed to merge anything until a human has looked at it. And if it is a behavioral fix or a big change, the SME has to sign off. That’s my team’s rule. Not only that, I built a fixture factory that Claude has access to. I built a headless integration with our product, so when Claude is changing behavior or documenting a new API or whatever, it can go run those API calls on its own in the fixture factory against the special sandbox. So it’s got sandbox credentials, and it will interact with our API product. And so everything is validated before I get brought into the loop. So my loop, to close this loop now: I have a ticket, I read the ticket, I fix anything that looks funky. I then mark it with a label that says doc bot. I say, okay, Claude, go. I have a script that I run that loads a special Claude permission file, right? And it goes and finds all those tickets that I’ve marked and given the blessing to do. It does a doc plan on each one, which in most cases is a very short paragraph, like, hey, I’m gonna update exactly this file, this is what I’m gonna change, etc. And I’m gonna write a changelog for this, and then I’m gonna notify this other person because it’s a breaking change, like the SDKs need to be generated again or whatever. I approve the doc plan or I push back on the doc plan. So I do read all of the doc plans, and then I say okay, and then I go to lunch and I come back to PRs. It works in worktrees. And so I have it doing anything that I would have handed off to a junior tech writer, and I review it like I would a junior tech writer’s work. And then from there I can say, okay, I need to tweak this skill a little bit. So we do have a lot of skills written to use. There is a style skill that catches stuff that straight regex can’t. So squishy human calls, I let Claude take the first stab using the skill, and then I come in.
Fabrizio (31:43)
Yeah. But you see, your process, I think, is a bit different than being just a consultant dropping templates there. You are the owner of your own factory, I think. That’s the point.
CT (31:55)
Way off the rails, I’m so sorry, y’all.
Fabrizio (31:57)
No, no, but I think the difference is significant, you know.
CT (32:03)
We do have templates, though, and templates are the starting… that’s the gateway drug. We start with these really serious templates for each content type. It cut down immediately on any kind of weird variation that Claude would do, because we have a CLI command that Claude uses to generate the new doc using the template, and it fills in the template instead of doing it from, I guess, memory or whatever you want to call it. So. Sorry, Tom, I’m…
Tom (32:28)
No, I love it, because you’ve given us a peek into what the writer’s role is. If you have all these other groups doing the ticket writing, doing the updates, there’s a fear of, what’s my value gonna be? But you just showed all these different workflows, the tooling, the style, the checks, and all this that the writer is now focused on.
CT (32:52)
Final review. And there’s the discretion part too, because, you know, we’ve all had to write notes about bug fixes and be really diplomatic. Stuff like that is where the human touch is really important. I’m letting the machine do a lot of the work, but I am then swooping in and having the final say. I do feel bad for people trying to get into the industry, though, ‘cause it’s gonna be a lot harder, I feel like. I’m only able to do this because I’ve been doing it for so long manually, and doing bash scripts since like 2012 or whatever. So the landscape is changing, and I do recognize that, and I do think it’s gonna be hard for a lot of writers. But that is one way. Work on making it so other people can’t create slop. Become an anti-slopagandist.
Tom (33:44)
Do you think that this writer would be generating a lot of skills that are tailored to a lot of different situations, and making those skills be enforced or used at scale? You didn’t actually go into skills in the book, so I’m curious about the role, but you clearly seem to have skills in your workflows.
CT (34:08)
Yeah, I’ve written a lot of skills. I’ve written a lot of external skills too, and then I’ve built test harnesses that nearly autonomously check those skills. They perform a real integration to make sure that the skills are accurate enough that most agent-harness combos can figure out what’s going on and not steer the readers too far off. So I’m a big fan of skills, but I was developing a lot of skills when I was writing the book, and I wasn’t ready to talk about it yet. I have skills for my monthly reporting. I have a skill in our doc repo. It lives in the doc repo because I didn’t want to create a new repo for it. I rock into the doc repo on the first of every month and I say, okay, here’s the ticket number for this report. Let’s go ahead and run the report. And it will go and access the PostHog API and pull the numbers it needs. There are scripts inside the skill. It’ll grab anything that it can, so it’ll get all of our GitHub stuff for all of our repos. It’ll grab all our Linear stats. I only have to go to two vendors that don’t have an API and pull it. It takes me five minutes now. This report literally used to take me eight hours to do. I did it the first business day of every month. And now it takes me like four minutes to kick it off, just to make sure I’ve got everything set up, and then to go grab those stats from those two vendors that don’t have a reporting API. And it summarizes everything, and then I go through and I read it, and I put the CT touch on it so it doesn’t sound like Claude did it. And I spot-check some of the numbers too, because if I’m putting my name on it, it needs to be accurate.
Fabrizio (35:52)
So we know the title of your next book, which will be Use the F-ing Skill, right?
CT (36:01)
Maybe. I’m very, very excited about skills in general. I think that tech writers have a natural… they should be doing skills, because skills are essentially instructions. For the most part, they’re instructions, even if they’re just lists of things to look out for, because that’s what a lot of my internal skills end up being. It’s like, hey, I know this API looks this way, but don’t brute-force this, because actually that filter only works if you use it this way. Stuff like that. And I think that skills really plug a gap there. How I came to this conclusion was, in building those public skills, I ran literally a thousand evals where I sat and watched the agent choke on stupid stuff. And I was like, okay, so I think the skill should mostly point to the docs, and the skill should have the places where, hey, don’t do it this way, even though it’s tempting. For example, auth. Things get caught up on auth all the time. Say you have an endpoint that has different auth standards. If it’s not in the skill, it might miss it, and it might go, hey, I can’t get a bearer token to work here. Well, that’s because that’s just a request token endpoint. Sorry. You wouldn’t have known that if you skipped the docs. So yeah.
Tom (37:16)
I’m glad that you’re a big fan of skills, because I also love writing skills. I feel like I want to write a new skill every day to do some new thing. It’s kind of fun to see what process can suddenly become easier.
CT (37:30)
You have to maintain them. That’s the problem. If it’s not a throwaway, you have to keep it up to date.
Tom (37:37)
Right, right. And I’m not creating a new skill every day. I am improving the existing ones. Okay, so here’s a scenario. This is a very sincere question. I created a skill at work called fix doc bugs. The idea is that it’s gonna handle tickets that are coming in, and it’s got a lot of logic in there, right? Now here’s the question, though. I can use this skill on fifty bugs and wake up the next morning, or actually in the next couple hours, and they’re done. There are change lists already for me, PRs already for me to look at. But since I haven’t done the cognitive work to even understand the tickets in the first place, I’m coming to these PRs, we call them change lists, cold, and they’re very hard to evaluate. A lot of them are deeply technical. So I basically just figure out who the right SME is, and the skill actually dives into file histories and identifies it, and I send it out. And then once the SME reviews it, and maybe another writer who’s a specialist in that area reviews it, I submit it. All with very little understanding of what’s even going on. I was just reading an article this morning by Ezra Klein, who uses this term, gradual disempowerment. I am becoming less and less capable because the AI is doing more and more of the lifting. And unless I wanna just focus on one or two tickets a day that I deeply understand, I will never get to the velocity that’s gonna move the needle by trying to understand everything. What do you think about that scenario? Is this just the way it is, that I’m just gonna be pushing buttons and finding the right SME and sending it out and just trusting in AI?
CT (39:36)
I can’t tell you what to do. What I will say is that I’m not interested in being a meat proxy. The nature of my role is that I need to deeply understand the product that I’m working with. And again, I work a lot of these bugs without fully understanding everything about them. Some of ours are complicated, some of ours are small. I know enough about our product, though, that I could figure out what’s going on. I’m not advocating for going and getting deep knowledge on all 100 bugs. I am advocating for knowing the product well enough that you will know when to tag someone else in. I’m also not a huge fan of letting AI do a bunch of work and handing it to an SME without me first looking at it and it passing the sniff test, because it makes me want to riot when people do that to me. But people are handing me slop. So that’s all I would say, is make sure you’re not giving people slop. I need to know a lot about the product. So I do occasionally pull a bug ticket out of the queue and work it manually, just to stay sharp. I go in my little editor and I remember my git commands myself. I don’t do it super often. I just do it to make sure that I haven’t lost that part of my brain, because I’m definitely not trying to just be a meat proxy at this point.
Fabrizio (41:02)
But I still think that… I was sending these text snippets again from that Claude Code post, which really struck me. They said that nobody on the team keeps a complete mental model of Claude Code in their head, and we don’t think anyone needs to. So that’s a big statement. And they say that when someone wants to understand a part of it, they just ask Claude to write an explainer, right? And I found myself doing this a lot with the products where I work. And I think part of this era we’re going through is accepting that we cannot understand the whole picture, and that it’s mostly fine to live with uncertainty. But I know you’re a philosopher, so maybe you have some idea about that.
CT (41:49)
I do. For me, part of the reason that humans still belong in tech writing is because humans are still using your products. Most of us. I mean, I’m sure there’s something out there that’s just a bunch of bots talking to each other. But in order to cater to humans in any way, shape, or form… and I know, like, eighty percent of our readers now are agents. Yeah, but that other twenty percent are the ones paying for the service. You have to have a level of empathy with your readers in order to serve them well. And I think in order to do that, you have to have an idea of how your whole product hangs together. And again, this is different. One of my writers, he’s not so junior now, he owns our embedded components fully. I gave him a whole product area. I have no idea what’s going on in that product area. I said, Elijah, you own this now. Don’t ask me about it. Get somebody else to review it, I don’t want to talk about it. So I don’t understand embedded components, but I understand how the embedded components fit in the rest of the product, if that makes sense. So I think there’s levels.
Fabrizio (42:49)
My God, yeah, we’re all becoming managers.
CT (42:54)
Yeah. Essentially. No, that’s why I think I’m doing so well with AI, is because I’ve just immediately treated it like a junior writer that I’m coaching. It’s a little bit easier, ‘cause I don’t have to tell them to brush their teeth.
Tom (43:11)
You do say in the book that systems thinking is, quote, “probably the biggest thing,” unquote, that you would look for in hiring a first writer. Can you talk a little bit about what systems thinking is and why you think it’s so important? So many engineering teams are very siloed on the APIs they create or develop. You said tech writers are specialized. You’ve got one person who does the embedded components. Maybe they know that so well that they can tackle anything that comes in about embedded components, but you step outside that circle and it’s like, I don’t know. So systems thinking, why do you think it’s important?
CT (43:54)
It’s important for a first hire at a company. If you’re bringing somebody in to fix your docs, build your docs, build out your devrel function, whatever, get your content in order, you need somebody who understands how that content relates to the rest of your business, relates to your customers, relates to your internal customers. You have to have somebody who understands that nothing in a business exists on its own. There’s a great book called Thinking in Systems by Donella Meadows that I would recommend reading. My team does a quarterly book club, and we each pick our own book and write a book report on it. And mine this last quarter was Thinking in Systems, so I reread it. It’s a great book to teach you how everything fits together. Not all tech writers need to know how everything fits together. If you’re just starting your career out or whatever, you’re just working on one product, ignore me. But eventually, if you want to be in charge of the docs or you want to keep moving up in your career, it behooves you to understand how your docs fit in with the rest of the product that you’re working on and the rest of the company. And it helps if you have a way of thinking in systems, thinking how everything impacts everything else, because you treat it like an organism, basically. So yeah.
Fabrizio (45:11)
And interestingly, these are also the hardest pieces for AI to write. I think these are the pieces where a writer can really shine, and AI cannot just get it, you know.
CT (45:23)
With Shoal Run, I’ve literally not manually written any of the documentation. And you know what I’m actually dreading? Because even Astra and Opus… Opus, what’s the… Fable?
Fabrizio (45:34)
Yeah. Fable.
CT (45:37)
They both did not understand. I spent a hundred dollars on Fable to see what it could do with docs, because I’m treating this as a big art project experiment, right? I want to see how it does. I have to go through and rewrite all the docs, and I need to put them in the right order, because it can’t even describe the thing it built itself in an intelligible way. It put breadcrumbs in a section on visual components in the docs. It put breadcrumbs there instead of navigation, even though it’s a navigation component. It said, yeah, that’s a component. It’s not. It doesn’t even follow the right format. What are you doing? So even our most expensive frontier models that we have access to, just as normal people, can’t properly do IA for a very small project. I only have like two hundred pages of content, and even with my guidance… I’ve already written the scaffolding for all of this as a skill, and it still needs checks.
Tom (46:39)
The systems thinking element is really a tough one. I wanna add one more layer to this. We started analyzing chat logs from AI sessions on people trying to build stuff with our product. And we found that a lot of the failures happen when people try to do cross-product workflows. There’s just not great guidance from the AI when you’re trying to move across products. And… wait, hey, Fabri, I hear your clickety-clackety. You might want to… sorry.
Fabrizio (47:13)
Sorry. Yeah, just taking some notes.
Tom (47:16)
So the problem is, how do you get the AI to understand cross-product workflows? Well, that’s difficult. There’s Conway’s law, which says that products reflect the org chart, and it’s absolutely true. Every org has their product, and they don’t think about users using that product plus three other products outside their org. So there’s never any documentation that stitches them all together. And I certainly don’t know that. Very few people have cross-product understanding of how all the pieces fit together in a big organization. And I don’t even know how I’d get that, because every engineering team just owns their little piece of the pie. Very few people have that info. So how do you get it?
CT (48:07)
I would advocate for having people who are generalists. This is how I’m handling this at my job: using AI for as much of my work as I theoretically can, to the point that it doesn’t create extra work for me or anybody else. That frees up time for me to figure out how to smooth those gaps. For example, I’m working on a cross-product flow, and our product’s a lot smaller than what you probably work on. But we have Pay In and Pay Out and Pay Ops, and I’m having to create a solution that touches a lot of these things. So I’ve just had to sit down and craft literal guides for it, to give the AI something to grab onto. Like, here’s how, if you were enabling these two services, this is what you need, and really crafting it together. I’m trying to solve this a little bit with Shoal Run, because I have an idea for this concept of ingredients, recipes, and then cookbooks, and having them glom together automatically. But it involves a lot of metadata, so I don’t know how automatic it’s gonna be. But this is a problem everywhere, I think. And that’s why I think it’s important to specialize, but also be a generalist who understands other areas of the product, unless it’s embedded components, and then you just let Elijah handle it. I find them so boring. I don’t like visual components.
Fabrizio (49:32)
Embedded components, bye. Yeah.
CT (49:34)
So… but I think it’s good to be a silo bridger, and I think that’s where I expect myself to fit in as tech writing changes. I need to be the one who knows how all this works, because it’s just everybody’s Claude talking to everybody else’s Claude, you know, and somebody needs to understand where the connections are. And that’s where the systems thinking comes in.
Fabrizio (49:58)
So kind of a humanist, which is, you know…
CT (50:00)
Yeah, I guess. I don’t really know what that word means, but it sounds good.
Fabrizio (50:03)
Well, the point I was kind of arguing for in my last blog post is that, you know, go and study the humanities, get some philosophy book, get some knowledge of something that is not too deep and technical. I think it helps.
CT (50:18)
I’m grateful every day for my philosophy degree. I know I’ve told you this before.
Fabrizio (50:21)
Yeah, I know. We know.
Tom (50:24)
Well, let’s wrap up here. CT, tell people how they can find the book, WTFM. It does come in different formats. I have the paperback version, and it’s super easy to read. I like print because I can mark up things. And tell us when you’re gonna record the audio version, you know.
CT (50:44)
No. So you can find WTFM free online. I’ve made a beautiful site for it. It’s wtfmbook.com, and you can read it there. If you insist on purchasing an ebook or a printed copy, there’s a link there. You can click the link, and it’ll take you to Amazon. If you don’t want to buy from Amazon, I don’t have an answer for you, because I couldn’t figure out any of the other publishing places. So it’s only on Amazon right now. Yeah, that’s pretty much it. Easy.
Tom (51:19)
All right. Well, thank you so much, CT. Thank you, Fabri. Really appreciated this discussion, and we’ll post the show online, with all the notes and the links, very soon.
CT (51:30)
Thanks so much for having me again.
Fabrizio (51:32)
Thank you.
Tom (51:32)
Thanks, CT. Thanks, Fabri.
About Tom Johnson
I'm an API technical writer based in the Seattle area. On this blog, I write about topics related to technical writing and communication — such as software documentation, API documentation, AI, information architecture, content strategy, writing processes, plain language, tech comm careers, and more. Check out my API documentation course if you're looking for more info about documenting APIs. Or see my posts on AI and AI course section for more on the latest in AI and tech comm.
If you're a technical writer and want to keep on top of the latest trends in the tech comm, be sure to subscribe to email updates below. You can also learn more about me or contact me. Finally, note that the opinions I express on my blog are my own points of view, not that of my employer.